An agent team that ships Amazon listings
A product listing on Amazon looks like one page. Behind it are about ten jobs: find out what the product really is, see what the competition says and charges, work out who buys it and why, write a title and five bullets under hard byte limits, design nine images, build the A+ section further down the page, and push it all through an API that rejects anything slightly off.
In a small company one person does all ten, badly, on a Sunday. I wanted to know how far a team of specialised agents could take it. The answer: a folder of phone photos in, a live listing out, with me approving at the gates instead of doing the work.
One agent per job, one file per handoff
The first version was one big agent that did everything. It worked for one product and fell apart on the second. Instructions that were loaded once at the start faded over a long session, intermediate results piled up in its context, and by image eight it was working from memory of rules instead of the rules.
What works is a team where every member has one job and a file contract:
| agent | reads | writes |
|---|---|---|
| researcher | the intake folder | the exact product, every reseller, their prices, specs, copy and images |
| marketer | the research | buyer personas, keywords, price plan, image scenes |
| copywriter | facts + marketer brief | title, bullets, backend keywords, validated against the live schema |
| designer | facts + marketer brief + photos | nine gallery images, three variants each |
| publisher | everything above | the API calls: preview first, live only after approval |
| orchestrator | the state table | which stage is next, and whether it is allowed to run |
Agents never pass their context to each other. They pass files: a facts ledger, a research database, a JSON brief cut to the consumer’s role. The orchestrator only ever sees short reports, never the pixels. That one change made long runs stable.
The facts ledger: no number without a source
The rule that carries the whole system: every number that appears anywhere in the listing must come from one file, and every entry in that file names its source: the data sheet, the manual, a measurement, the carton print.
Language models are very good at producing plausible specifications. “Load capacity 150 kg” reads perfectly well and might be wrong. So the copywriter may only use numbers from the ledger, and a QA pass reads the finished images back and rejects any number it cannot find there. One run caught the marketing layer still saying 2.85 kg after the product had been re-weighed at 2.60 kg. The ledger was right, the persona text was stale, and the check said so.
The researcher: find the exact product, not a lookalike
Most of what gets sold in this segment is made by a handful of factories and sold under dozens of brands. If you know the factory model, you know every competitor that sells the identical item, and their copy, specs, prices and manuals become research material.
The researcher identifies the model from the photos, then runs reverse image search and model-number search across several engines. Different engines have different regional bias: one found the whole US reseller layer the others missed. It then sorts matches into exact and variant by a hard spec fingerprint.
The lesson here came from a mistake. One competitor was filed as an exact match because three
specs coincided. The pictures showed a different construction. Now an exact verdict requires
the agent to actually look at both products side by side; a match that was never looked at is
unverified, not exact.
The marketer: personas, and keywords that people actually type
The marketer turns research into decisions. For a shower stool it came up with five buyer personas: the older person buying for themselves, the adult daughter buying for a parent (the largest group), the caring partner, temporary use after surgery, and heavier users who need a higher load limit that none of the competitors offered.
Two things make this more than a brainstorm:
- Keywords are gated against reality. A model will happily invent synonyms and “common misspellings”. Only terms that show up verbatim in real autocomplete suggestions survive. Of the invented misspellings, not one did. Where available, Amazon’s own weekly search-term report (well over a million terms for one marketplace) ranks what is left.
- Prices come from observed offers, not vibes. The price plan takes the median of real competitor prices, picks the nearest charm price just below it, and sets the reference price from the upper quartile of what was actually seen, capped, with the legal rules for reference prices printed next to it. On the first product it landed on exactly the price I had picked by hand, which I took as an independent check rather than a coincidence.
The designer: whole images, three at a time
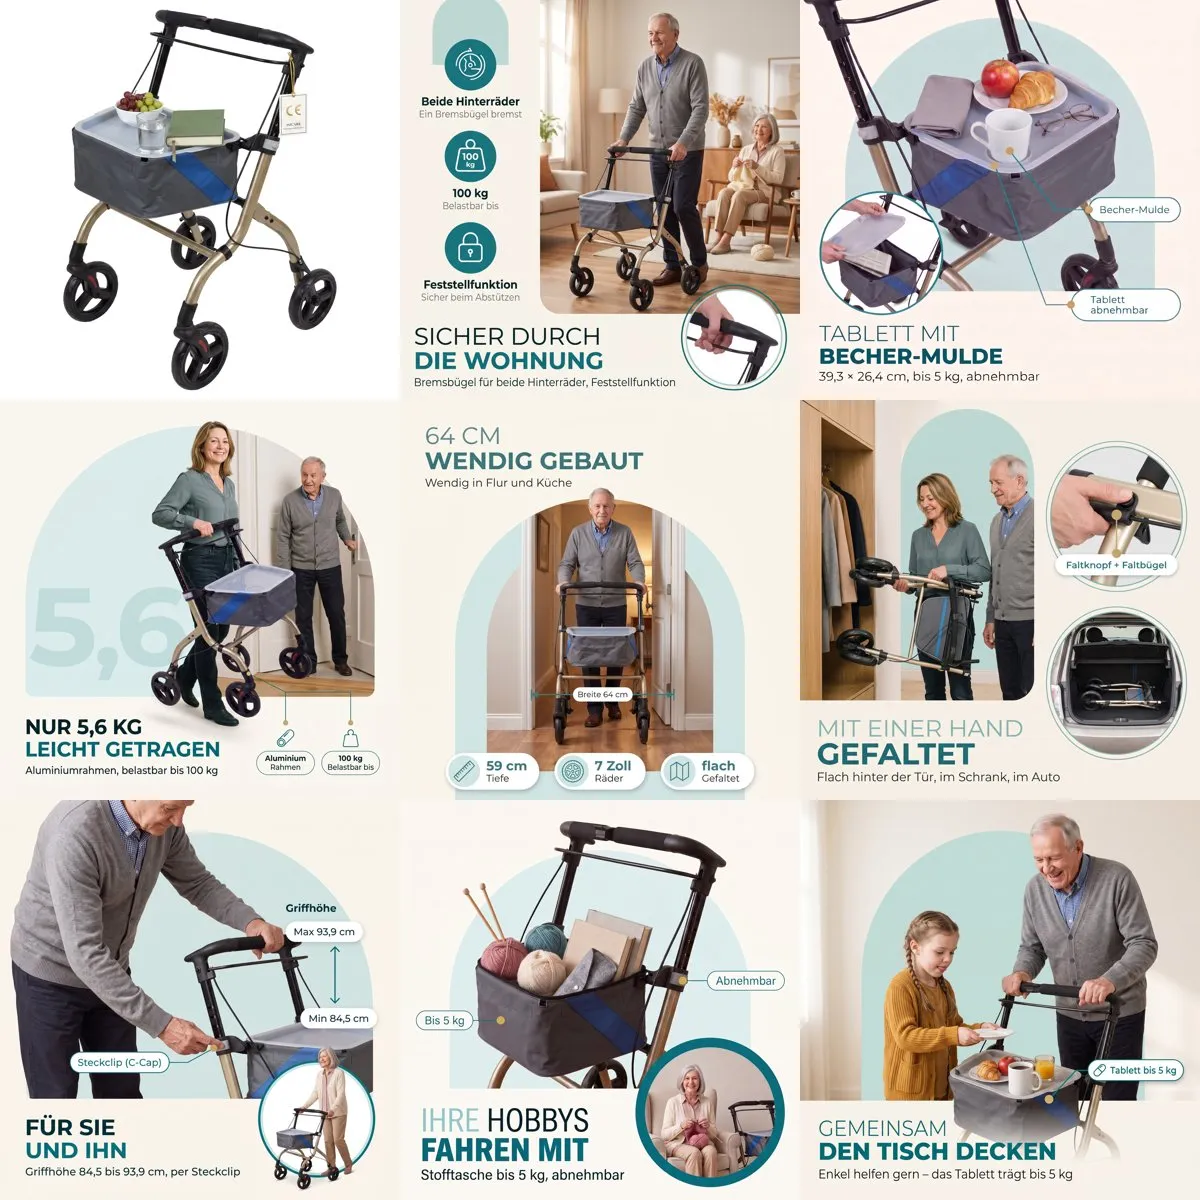
The first image attempt put text boxes on top of a reused product photo. It looked sterile, and I said so. What works now: an image model renders the entire image, meaning scene, product, layout and the German headline, from a written brief. Three variants per slot, and I pick.
A few lessons that only show up in practice:
- Say what you mean about bodies and objects. Describing a person with “the stool beside him” made the model add a second stool in every variant. “He sits on the single stool, exactly one in the frame” fixed it.
- Umlauts must be real characters. Prompts written in ASCII (“Sitzhoehe”) got painted into the artwork literally.
- Edit, don’t re-roll. A fix is an edit pass on the approved image with one instruction. Small type damaged by an edit gets patched back from the original pixels instead of regenerated.
- Faithfulness is a gate. Every render is compared with the real product photos. A handle that changed shape is a rejection, however nice the lighting.
- Props need a reason. Each scene card lists its props with a
why, and a list of forbidden props (no backrest on a stool that has none, no tools for a tool-free assembly). The forbidden list is also a QA check.
Humans at the gates
Seven of the ten stages cannot complete without my explicit OK: the facts, the copy, the images, the price, the live push. The agents do the work; they don’t get to decide that the work is good enough. Anything that touches money or a public page waits for a person.
That is not a limitation to engineer away later. It is the design. An agent that can publish on its own will, at some point, publish something wrong at scale.
Where this goes: compliance as the source of truth
For regulated products the stakes are higher. A medical device’s intended purpose and safety claims are legally fixed, and marketing copy is not allowed to drift from them. That is what Sanopta is built around: regulatory data (device identifiers, declarations of conformity, approved claims) is locked behind a compliance gate, and all commercial output (images, copy, A+, listings) is generated from that locked data and nothing else.
Architecturally it is the same pattern as above, grown up:
- the web app never talks to an agent directly; it writes a job row to a queue in the database,
- a containerised worker picks it up, runs the right agent for the job type and writes the results back to storage,
- one worker image holds many agents (IFU builder, declaration generator, listing agents) and scales by concurrency and replicas,
- keys live as sealed secrets on the worker, never in the frontend, never in git.
If you want to build one
- Split by job, hand off by file. If you can’t write down what an agent reads and writes, it is doing too much.
- Keep one ledger of facts and make every other agent a consumer of it.
- Gate model output against the world: autocomplete, observed prices, the real photo.
- Put humans where money or reputation is at stake, and nowhere else.
None of this depends on a particular model vendor. The pieces are a language model, an image model, a database, a queue and an API client. The discipline is the product.